Feasibility Scoring: How to Add Constraints Without Killing Creativity14 min read
Someone senior asks a fair question, so the scorecard gets a feasibility column. A year later, the approved list is work which the team could have built without one.
The symptoms are easy to recognise:
- Bold submissions stall at enrichment and quietly expire.
- Scoring sessions turn into arguments about who has capacity next quarter.
- The portfolio fills with careful extensions of what already works.
- No single meeting explains where the ambition went.
Feasibility belongs on any scorecard that decides where money goes. Without it, the shortlist fills with work nobody can resource.
The damage comes from how constraints get added, not from having them. Which ones are absolute, where they enter, what the number measures, how finely it’s scored.
Four scorecard decisions settle them. Get them right and the safe option stops winning by default – get them wrong and little changes.
Why a Feasibility Column Quietly Selects for the Safe Option
The idea-selection stage behaves differently from generation. The experimental record on how people choose isn’t flattering.
Selectors Reach for What’s Feasible
A 2010 study of idea selection describes “the strong tendency … to select feasible and desirable ideas, at the cost of originality.”
Instructing selectors to prioritise creativity shifted what they chose. It also lowered satisfaction and the rated effectiveness of their picks (the authors’ effectiveness-originality trade-off).
The feasibility column is where that pull turns procedural:
- A preference nobody has to defend gets its own box on the form.
- The box gets a weight, and the weight gets a number.
- The number is averaged, reported and read as though it were a measurement.
You’ll feel the pull in the room long before anyone says it out loud. By then, it’s arithmetic, and arguing with it means arguing with the form.
An earlier 2006 experiment by the same team found that idea selection “was not significantly better than chance.”
Those 2 results say different things and shouldn’t be stacked. One is about accuracy at chance level, the other about a directional pull.
None of this makes an argument for removing feasibility entirely. The design question is the point at which that judgement is allowed to act.
Where Explicit Criteria Change the Picture
Amabile’s 1979 experiment had undergraduates make artwork under expected evaluation. Judges rated that work significantly lower on creativity.
One group escaped it, told explicitly how to make work that would be judged creative. Opaque criteria seem to do the damage, and publishing yours can do 3 things:
- Reduce guesswork about what reviewers want.
- Remove your freedom to move the goalposts mid-cycle.
- Show submitters which unknowns to name, and which ones disqualify.
The rubric therefore doubles as a brief for the people submitting. It describes what gets funded, in the words you chose.
Contributors read it as a description of what gets funded, and a careless rubric brings back carefully unambitious ideas.
That exception carries a lot of weight here. It’s one condition in one study, so a published rubric is a reasonable bet, not a proven fix.
What the Evidence Actually Says About Constraints
Constraints have a better reputation in the research than they do in the scoring room. The evidence doesn’t support a simple good-or-bad verdict.
A 2019 Journal of Management review reports an inverted U between constraints and creativity. Too little suppresses it, and too much does the same.
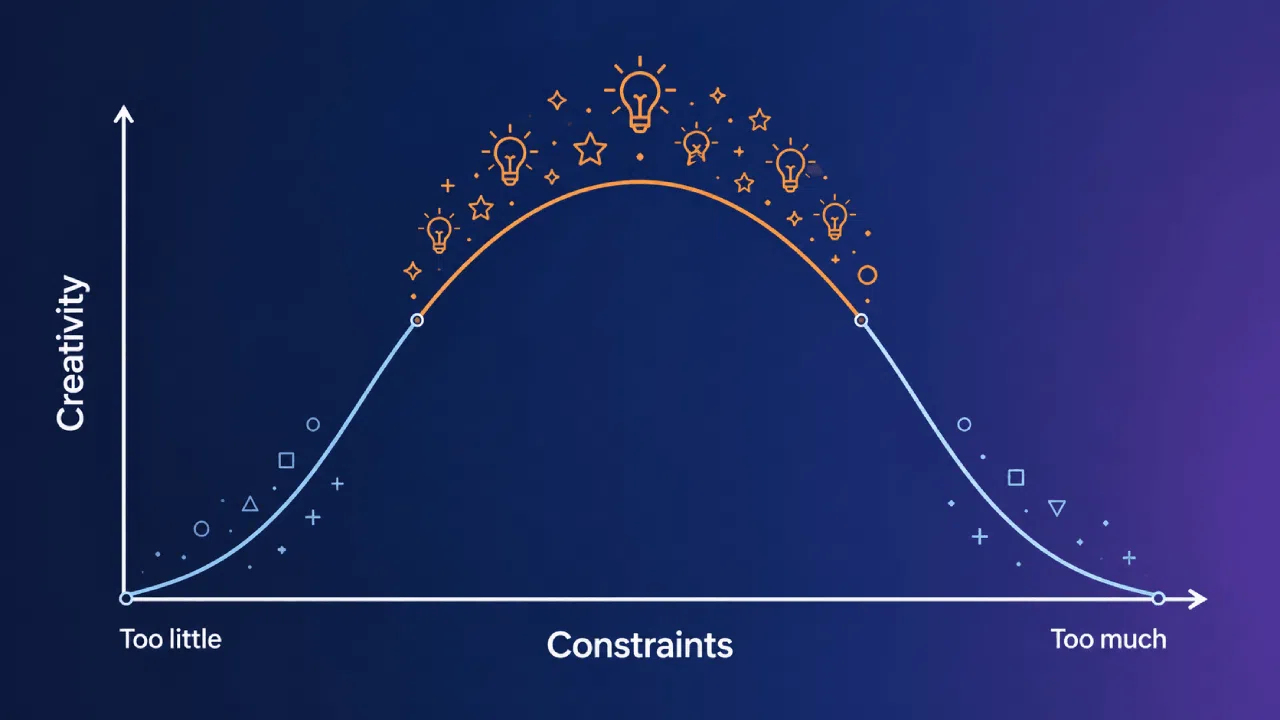
To be fair, that’s a synthesis of other work, so it gives a shape without a calibratable turning point. Here’s one application to scorecard design:
| How the scorecard is set | What it looks like in practice | What can happen to the idea pool |
|---|---|---|
| Few stated limits | No absolutes, open scoring | Unbuildable submissions, no shared standard |
| A handful of absolutes | A short must-meet list, coarse levels | Ambitious ideas can still clear intake |
| A long must-meet list | Many must-meets, fine-grained scoring | Safe variations of current work |
In Haught-Tromp’s 2017 rhyme studies, constrained verses were rated more creative than unconstrained ones. Means were 5.18 to 4.29 in study one, 5.13 to 4.36 in study two.
Haught-Tromp also found a carryover effect, with constrained practice raising creativity on later unconstrained trials. It’s a rhyming task, so read the transfer to creative practice narrowly.
Rosso’s 2014 field study of four R&D teams found constraints helping some teams and suppressing others.
The difference sat in whether the surrounding dynamics were enabling. Applying that mechanism to scorecards, a must-meet list can land differently in different teams.
Separate Hard Constraints From Scored Feasibility
Cooper and Edgett’s 2006 paper notes that gate scorecards “can include must-meet (mandatory) as well as should-meet (desirable) criteria.” Putting both in one column is where the trouble starts.
| Criterion type | What it answers | Who answers it | What a “no” means | Where it sits in the funnel |
|---|---|---|---|---|
| Hard constraint | Can we do this at all? | Legal, security, or strategy owner | The idea stops, whatever else it scores | At intake, before scoring |
| Scored criterion | How costly is it to find out? | The reviewing panel | A lower score, not an automatic exit | After enrichment, before funding |
Must-meet criteria are binary, with no partial credit anywhere. They’re checked before anything is scored, so they can’t contaminate a number.
Well, that ordering is the whole point. A hard constraint applied after scoring becomes a late veto over an option that was never eligible.
The Test for a Hard Constraint
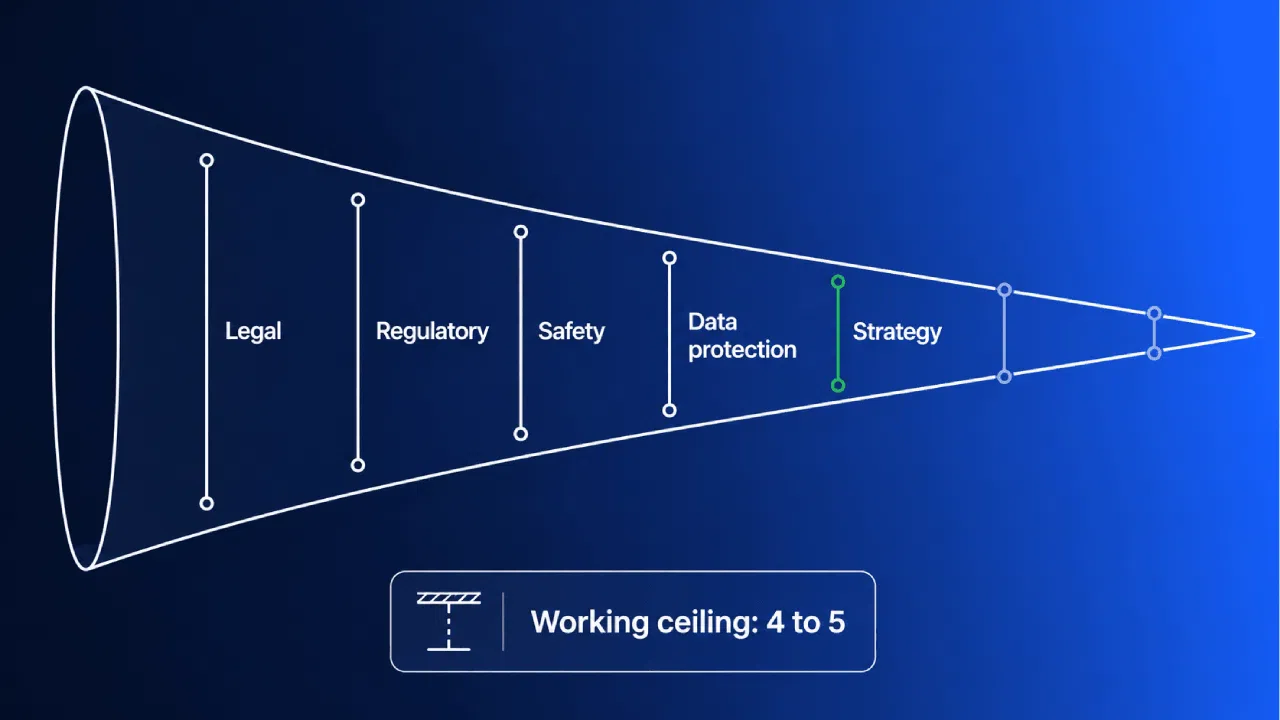
For innovation risk, reserve hard constraints for legal, regulatory, safety, data-protection or strategic requirements that genuinely end the conversation.
The test here is blunt: if a “no” is arguable, it isn’t a hard constraint and it belongs in scoring instead.
Why the List Shouldn’t Grow
Use 4 or 5 hard constraints as a working ceiling. Each extra one narrows the funnel before anyone has read the idea.
Cooper and Edgett are also useful on what happens downstream. Once a project begins, they write, “there is very little chance that it will ever be killed.”
Their paper gives no quantified waste figure, so treat that as directional. It does explain why kill criteria belong upstream of any real commitment.
Score the Cost of Finding Out, Not the Odds of Success
Early feasibility scores are forecasts about work that isn’t fully scoped. Boehm’s cone of uncertainty puts the range at roughly 0.25x to 4x in the feasibility phase.
It tightens to about 0.67x to 1.5x by the requirements specification, in Boehm’s own 2013 restatement. Three things follow:
- A number scored at intake is a forecast of a forecast.
- A ten-point scale implies a confidence that range can’t carry.
- Direction and rough order of magnitude still hold, and nothing finer.
The estimates come from software work, so the read-across to other early scoping is an assumption.
Precision improves as the work gets specified in detail. Until then the scale is promising more than the evidence delivers.
None of that makes an early estimate useless. It makes the scale you record it on the thing to get right.
When Early Estimates Run Optimistic
Optimism in early estimates is documented well outside innovation portfolios. A 2003 study of 258 transport projects across 20 nations reported average escalation by project type:
| Project type | Average cost escalation |
|---|---|
| Rail | 45% |
| Fixed links | 34% |
| Roads | 20% |
The authors conclude that cost escalation “is the rule rather than the exception.” That’s transport infrastructure, borrowed here as an analogy.
How large the effect gets inside a corporate portfolio is unknown. The direction is what travels, and it argues against asking a scorecard for odds.
Odds of success give way to cost of finding out, and to speed. On feasibility, a 3-week test should outscore a confident guess.
McGrath and MacMillan’s 1995 discovery-driven planning opens on big losses in unknown territory, Disney’s European park past $1B by 1994 and FedEx’s Zapmail at $600M.
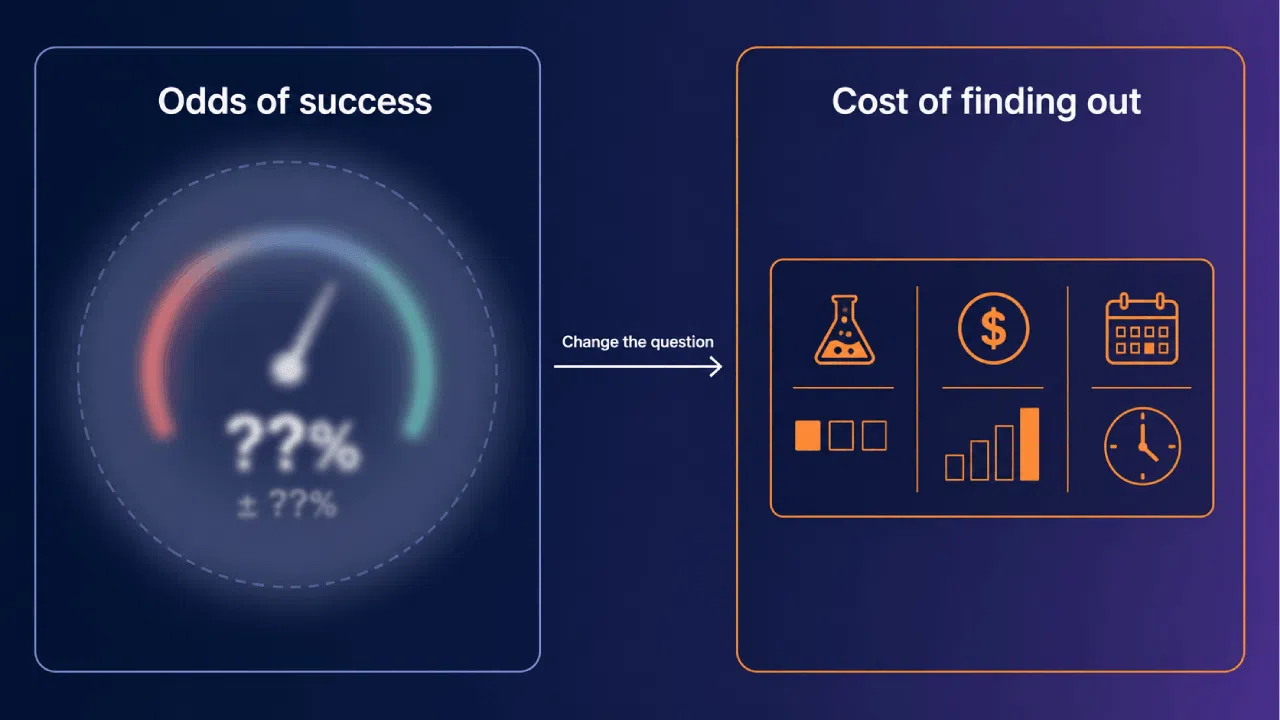
Their fix is better planning and control tools. On feasibility, a cheap-to-test idea with a large unknown should outscore an expensive-to-test one.
Designing the Rubric So It Doesn’t Flatten Everything
Use 3 anchored levels instead of a 1-10 slider. A 10-point scale invites arithmetic the underlying judgement can’t support.
Tversky and Kahneman’s 1974 study showed anchors shifting estimates. Groups anchored at 10 and 65 gave median estimates of 25% and 45% for African countries in the UN.
Honestly, that’s general estimation research, and the read-across is mine. Finer scales plausibly leave raters more room to drift toward the number they see first.
Anchor Each Level in Observable Evidence
An anchored level names evidence a reviewer can check, so “moderately feasible” doesn’t qualify. Rank the levels by cost to settle the unknown, not by its size.
| Level | What has to be true | Evidence a reviewer can check | What it means at this stage |
|---|---|---|---|
| Cheap to settle | One test settles the main unknown | A named assumption, a test plan, a date | Eligible for a test this cycle |
| Costly to settle | Settling it needs a build or a partner | A test plan with real cost attached | Needs a staged budget if selected |
| Not yet scopeable | We can’t say what would break | No comparable work, no test designed | Send it back to enrichment |
The classic 1980 review of behaviourally anchored scales, by Jacobs, Kafry and Zedeck, found BARS “is no better or worse than other methods when assessed on a quantitative basis.”
The same review credits the format with “greater potential” on utilization and qualitative criteria. So anchors buy you shared interpretation while measurement precision stays out of reach.
Keep the Axes Separate and the Criteria Few
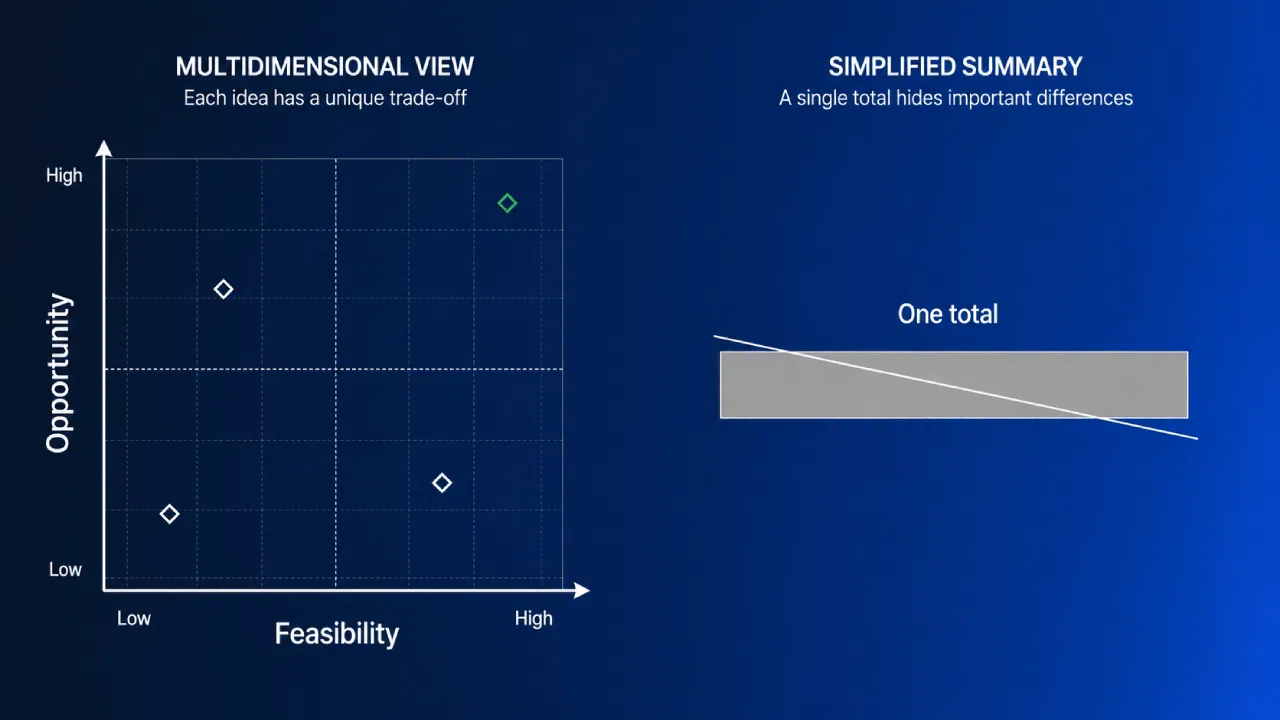
Cambridge’s Institute for Manufacturing stresses treating opportunity and feasibility separately. Keep both results visible, because a single total hides the trade-off the decision is about.
Thorndike’s 1920 paper on rating errors reports judgements “apparently affected by a marked tendency to think of the person in general as rather good or rather inferior.”
Those were ratings of industrial employees, so the transfer is inference. The risk on a scorecard is that one strong impression can colour both axes.
The IfM’s controlled convergence guidance puts “a good target of high level criteria… around 10,” offered as practitioner guidance from a named institution, with no validated ceiling behind it.
Where Feasibility Enters the Funnel
At idea intake, check the hard constraints and nothing else. A score on an idea nobody has examined describes the writer, not the work.
Feasibility belongs in the evaluation step after enrichment, once someone has looked at the thing. That sits before any commitment of real money.
The sequence runs in four stops:
- Intake: hard constraints only, checked and logged.
- Enrichment: the submitter and a reviewer put evidence behind the riskiest assumptions.
- Scored review: value and feasibility scored on separate axes, with any weights kept inside each axis.
- Funding gate: both axis results compared without summing them, then the decision and reasoning recorded.
A 2019 study of anticipated evaluation found groups producing fewer ideas under it, 21.03 against 32.95 on average.
The same groups explored fewer categories of ideas, 11.65 against 15.05. Novelty scores did not differ significantly, which is the honest reading of it.
So the argument concerns search space, not a demonstrated drop in novelty. Groups anticipating evaluation generated less and ranged less widely.
That leaves fewer chances for a genuinely original idea to reach the scorecard.
Publish scoring criteria and timing in the mission brief, then repeat non-negotiables on the form. Anticipated evaluation costs volume, and vagueness can cost the ideas worth having.
Four Ways a Feasibility Score Goes Wrong
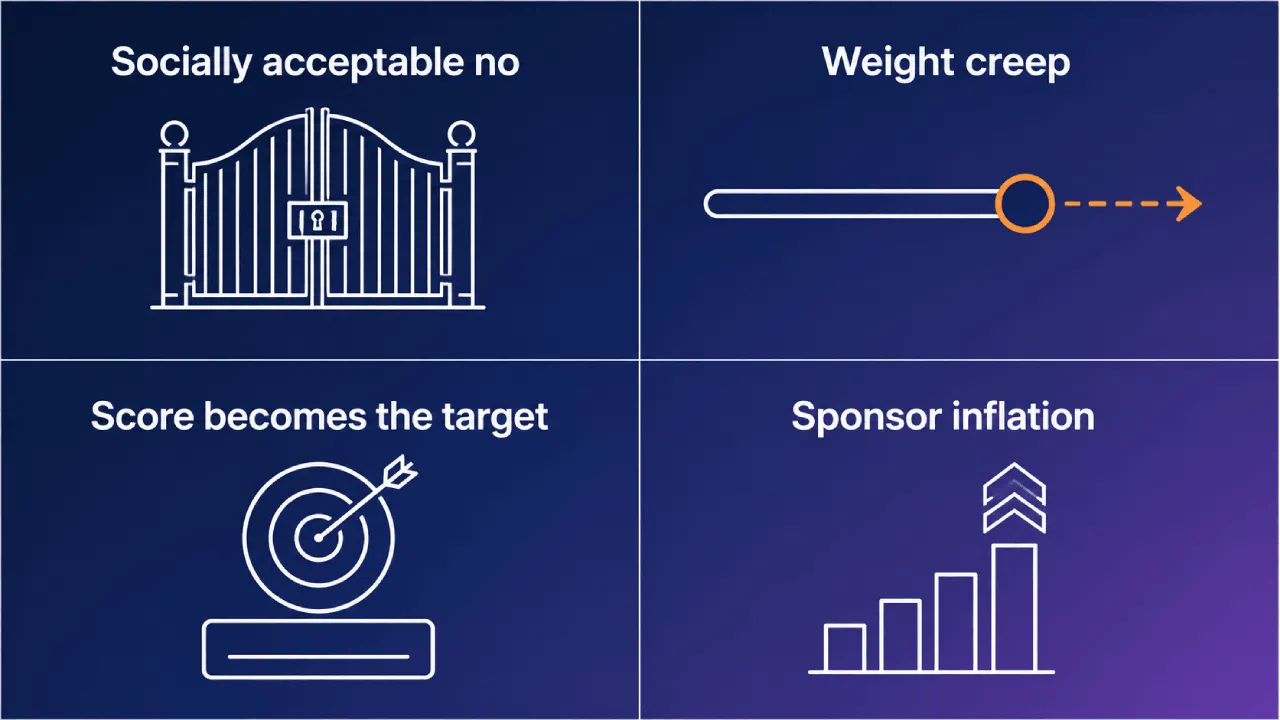
Four failure patterns are worth designing against, a narrower set than the governance anti-patterns that surround them. Each is a scoring artefact that doesn’t announce itself.
Feasibility as a Socially Acceptable No
Feasibility gives a reviewer a reason that goes undefended. “Too hard right now” closes a conversation that “I’d rather not” couldn’t.
Watch for reviewers whose feasibility scores track their workload more closely than the idea in front of them.
The number can be sincere, and what produced it still stays invisible until someone writes the anchors down.
An anchored level requires the reviewer to name what’s actually missing. Capacity next quarter is a schedule problem, and it belongs in a different conversation.
Weight Creep
Feasibility is the easiest criterion to justify out loud, so watch whether its weight creeps up. Put a date in the calendar for revisiting the weights.
The IfM’s weighting and rating guidance calls both weightings and ratings “subjective and arbitrary,” and the method “extremely sensitive to small changes.”
Publishing the weights next to the scores makes changes visible. If the first set looks wrong, use the objection to test its assumptions.
The Score Becomes the Target
Goodhart’s original formulation is drier than the version people quote: “Any observed statistical regularity will tend to collapse once pressure is placed upon it for control purposes.”
The familiar “when a measure becomes a target” phrasing is Marilyn Strathern’s 1997 restatement, and it’s worth attributing correctly.
Once submitters learn the rubric, they can write to it. That’s manageable when the rubric rewards evidence, and corrosive when it rewards adjectives.
Sponsor Inflation
Sponsor seniority is worth testing against the scores, since few reviewers enjoy giving a director’s proposal a two. Compare scores by sponsor level.
Ask reviewers to score independently before discussion, or blind the first pass. That protects the first number written down, though it slows the session.
A timestamped record makes changes in weights and scores easier to audit. That’s where the platform you score in earns its place.
Put the Constraints in Writing Before You Put Them in a Score
The rubric is a policy document whether or not you call it one. It tells people what kind of ambition survives contact with the funnel.
Four changes are worth making first:
- Split the must-meet constraints out and cap the list at five.
- Score the cost of settling the unknown, not the odds of success.
- Anchor feasibility on three levels, with value scored on a separate axis.
- Apply feasibility after enrichment, and publish the rubric, the weights and the record.
AI belongs in the drafting and the auditing. It can propose scorecard criteria from your strategy and flag scoring that drifts between reviewers.
Start with the must-meet list and cap it before the next scoring round. The rest of the rubric gets easier once that column stands on its own.
Our ebook on idea evaluation and governance walks the same pipeline from intake through to portfolio. It goes deeper on enrichment and scoring than one article can.
Or book a demo to see how Accept Mission handles scorecards, weighted criteria, and the timestamped records that make scoring drift visible.
Engage Your Circle: Share This Article on
Related Posts


In This Article
How mature is your innovation system?
Benchmark your governance, portfolio visibility, and decision making in minutes.
Start the benchmark →



 English
 Dutch
 Portuguese
 Spanish
 French
 German
 Arabic