From Intake to Insight: Reading Your Funnel as Evidence, Not a Queue14 min read
Last cycle your team scored four hundred ideas, funded nine, and archived the rest. The 391 that died were read once, as candidates.
A well-instrumented funnel can record four things:
- Who submitted, and from which part of the business
- What they submitted about, in their own words
- Where each idea died, and at which gate
- How long it sat before anyone replied
Read one at a time, those records are candidates for funding. Read together, they’re a map of where the organization keeps straining.
Four hundred submissions are four hundred observations about where contributors perceive wasted effort, customer friction, and processes under strain.
Read that as a queue, and the result is an empty queue. Read it as evidence, and the same export shapes next cycle’s budget.
What the Funnel Records That the Scorecard Doesn’t
A scorecard evaluates a single idea against criteria you set in advance. It supports triage, validation, and portfolio review.
The aggregate answers something the scorecard wasn’t designed to ask: what does this organization keep trying to fix?
Toyota’s suggestion system logged 810,000 submissions in 2023. The more useful artifact is fifty years older.
A category breakdown Toyota published in 1973, covering the preceding several years, ran like this:
- 70% on eliminating or simplifying production processes, or introducing automation
- 10% on improving product quality
- 10% on lowering the cost of materials
- 7% on simplifying business operations or internal forms
Read as a distribution, that split portrays where the work hurt, drawn by the people doing it. Decades on, it still names what the shop floor fought.
NASA’s Aviation Safety Reporting System has collected over 2.3 million reports since 1976. The program has issued more than 8,150 alert messages.
The 1981 sterile cockpit rule had considerable input from that system, by NASA’s own account. Individual reports can describe serious incidents, but each remains an isolated signal.
The aggregate informed federal policy. That’s a read a scorecard doesn’t ask for.
Half of the respondents self-reporting a leading innovation capability set targets and actively measure idea creation and conversion, against 39% of average respondents, Deloitte found in 2021.
| Read as a queue | Read as evidence | |
|---|---|---|
| Question it answers | Is this idea worth doing? | What does this organization keep trying to fix? |
| Unit of analysis | One submission | A full cycle’s intake |
| What it produces | A score and a gate decision | A distribution and a theme |
| Decision it supports | Fund, park, or kill | Where next year’s budget shifts |
Both views run off the same intake. Only one of them tells you where to point next year’s mandate.
A Theme Is a Budget Claim
Mintzberg and Waters drew the line in 1985. Deliberate strategies are the ones realized as intended, and emergent strategies are patterns realized despite intentions, or in their absence.
A funnel can surface signals of the emergent kind: patterns appearing outside prior intent, expressed in contributors’ own language.

Naming a theme is the deliberate act. It’s the moment a pattern gets absorbed into the plan and given a budget line.
The Pattern Moves Money Before Anyone Names It
At Intel, middle managers allocated more and more resources to specialty microprocessors and away from commoditizing DRAM, before leadership rewrote the official strategy.
Burgelman’s account has top management supporting that behavior before the corporate strategy actually changed. The pattern moved money before anyone named it.
That’s worth checking before you propose a reallocation. The shift may already be underway somewhere in the business.
Then your theme’s job is to catch up and put a number on it.
The Failure Mode Is a Relabeled Spreadsheet
A theme exercise can stop well short of a number. Research on innovation theater describes visible symbolic activity with no impact on the innovation process.

Renaming twelve categories into four domains can become theater. If nothing downstream changes, the exercise stayed symbolic.
Here’s the test worth applying before the slide gets made.
If a theme changes no allocation, owner, or stage gate, it’s a label. Cheap to produce, and easy to recognize as one.
Read the Distribution Before You Read the Ideas
For a few hundred submissions, the first pass can fit into an afternoon. Confirming what it turns up takes longer.
Five reads are worth running first:
- Concentration by category, and whether it shifted since last cycle
- Where each theme dies: intake, scoring, or the gate after the pilot
- Repeat submissions of the same complaint, filed by different people
- Convergence across departments that don’t talk to each other
- The gap between where submissions come from and where declared strategy points
Expect the second read to be the uncomfortable one. A theme repeatedly dying at one gate signals that the gate and the theme’s fit need investigation.
Maybe the criteria are unclear, maybe the sponsor’s missing, or maybe the theme costs more than that gate was ever built to approve.
Convergence deserves its own meeting. When finance, field service, and two plants file the same complaint independently, treat it as a system problem until something rules that out.
The fifth read gets political. When intake clusters away from declared strategy, the mismatch needs investigation and may be framed as communication.
That divergence is the theme worth taking upstairs. Run the same reads against last cycle’s export too, because a distribution without a comparison point is decoration.
Your Distribution Is Partly an Artifact of Your Own Replies
There’s a feedback loop underneath all of this. Feedback on last cycle’s ideas can shape the success of later submissions.
Researchers tracking 1,143 ideas over five years at an automotive company found success feedback and constructive idea-related failure feedback associated with higher future idea success.

Ideator-related failure feedback was associated with lower future idea success. Their advice is blunt: prioritize feedback on ideas rather than ideators.
A thin category can simply be one where the last three submitters got silence. The response log helps separate a quiet theme from a neglected one.
The Sample Isn’t the Organization
Evidence is only as good as its sample. Everything above assumes the funnel represents the organization, not just whoever felt safe and unbusy enough to submit.
A Harvard dissertation study followed crowdsourced ideation at a hospital cardiac center. The numbers are worth sitting with:
- 72 clinicians and staff submitted 138 ideas across the contest
- Of the 354 staff who completed the accompanying survey, a sample rather than the whole center, 11% took part in ideation
- 31% of those same respondents voted
A supportive learning environment, including appreciation for new ideas, welcoming differences, and allowing mistakes, tracked who participated. Perceived leadership support wasn’t significantly associated with participation.
The categories that show up thickest may be the ones owned by managers who respond well to being told something’s broken.
Who’s Actually in Your Sample
Almost 90% of the solutions from one company’s internal crowdsourcing challenge came from junior to mid-level employees, MIT Sloan Management Review reported in 2017.

About 30% came from support functions such as HR, IT, and finance. That’s useful signal, and it’s also a warning about coverage.
A high-volume intake can still miss senior operators; check the role mix. Volume hides composition.
Read the Silence
Campaign prompts shape what comes back. Treat a cost-heavy theme as campaign-specific signal until an unprompted baseline supports broader demand.
A business unit that submitted nothing is a data point, and you should expect the explanation to be uncomfortable.
Two plausible explanations are worth checking:
- The campaign didn’t reach them
- They didn’t believe anything would happen
Either finding would be actionable once checked. Read the funnel as evidence about attention as much as ideas.
Unlike a designed survey panel, ordinary funnel intake doesn’t automatically correct for missing groups. The missing input has to be collected directly.
Run targeted sessions with the quiet units, then write the coverage gaps down beside the numbers.
Where Clustering Helps and Where It Quietly Misleads
Four hundred submissions may be manageable by hand. With four thousand, the case for machine-assisted triage grows, depending on team capacity and cycle length.
Topic modeling groups submissions by language, proposes clusters, and gives a human something to argue with.
The honest question is how good those clusters are. A benchmark published by the team behind one LLM-enhanced topic modeling method puts numbers on it:
- Topic coherence: 70%, against 65% for BERTopic and 57% for LDA
- Topic diversity: 95.5%, against 85% for BERTopic and 72% for LDA
- Topic-word lists identically mapped to the same ground-truth category by at least three of four evaluators: 50%, against 25% for both baselines
Those are the 20-topic results, matching the test corpus’s own 20 categories. At 40 and 50 topics, the BERTopic baseline edges ahead on coherence.
That last line is the one that matters. For half of QualIT’s 20 topic-word lists, at least three evaluators independently chose the same ground-truth category.
And that’s on a public benchmark corpus, not on internal company text, which is messier and far more context-dependent.
Idea submissions can make the job harder. Many early-stage submissions are short, sometimes only one or two sentences, leaving little word co-occurrence to work from.
A survey of short-text methods notes that PLSA and LDA can’t solve this well, because the signal they depend on barely exists.
Machines Propose, People Dispose
IBM’s 2006 Innovation Jam still reads as a working model. 150,000 participants posted more than 46,000 ideas, across employees, partners, clients, and university researchers.

The company ran text-mining software. The write-up is candid: software-generated categories still needed human refinement into understandable themes.
The fix was headcount: IBM flew about 50 people to New York to narrow the output to 31 ideas. IBM launched 10 new businesses with $100 million seed.
Treat a cluster as a candidate, not as a finding. Confirmation costs human hours, and budgeting for those hours is part of the method.
Don’t Import Someone Else’s Ratio
Somewhere in your deck there’s probably a funnel ratio. It came from somewhere, and the somewhere is worth checking.
Stevens and Burley’s 1997 article in Research-Technology Management put the number at 3,000 raw ideas for one commercial success. Their chain runs like this:
- 3,000 raw ideas
- 300 shortlisted for a second stage
- 125 small projects
- 9 large projects
- 4 taken close to launch
- 1.7 actually launched
- 1 commercial success
It shows up in decks and vendor reports, and it’s paywalled. The method behind it isn’t something you can go and check.
Which hasn’t slowed it down. A number repeated often enough stops being asked for its evidence.
What Happens When Someone Tests a Ratio
Heinrich’s 300:29:1 safety triangle carried that authority for decades. A 2018 Risk Analysis study drew on more than 25,000 establishments over 13 years.
A pyramid was there, but its form depended on how severity was delineated. Where you draw the lines decides the ratios you get.
The 70/20/10 split has the same gravitational pull. Nagji and Tuff found outperformers allocating 70% to core, with returns running the inverse:
| Horizon | Share of innovation activity | Share of long-term returns |
|---|---|---|
| Core | 70% | 10% |
| Adjacent | 20% | 20% |
| Transformational | 10% | 70% |
The authors called 70-20-10 an average allocation, not a magic formula for all companies. That caveat travels less often than the split does.
Deloitte’s 2018 public-sector work shows the context dependence clearly. USAID’s Bureau for Global Health ran 70% to 90% core and adjacent, with 10% to 30% transformational.
Mission drove the ambition mix there, rather than market position. None of the ratios above came out of your funnel.
Getting a Theme Past a Leadership Team
A theme that survives analysis can still die in the room. BCG’s 2024 survey sizes the gap it has to cross.
Three findings sit behind the problem:
- Just 12% of companies report a strong link between business strategy and innovation strategy
- Strategy-led innovators achieve a share of revenue from new products 74% higher than weak-link companies
- 83% see innovation as a top-three priority, and 3% are ready to translate those priorities into results
A theme carries funnel evidence into the space between that 83% and that 3%, in a form a budget conversation can use.
It only does that when the theme is framed as a decision. Dutton and Ashford’s model of how issues get sold upward explains why.
They argue that issues framed as strategic are the ones top management treats as relevant, and that succinct framing draws more attention.
A theme presented as a category invites curiosity. A theme presented as a resource decision invites a verdict.
| What the theme needs | What that looks like |
|---|---|
| Evidence | Two cycles of distribution data, not one |
| A named strain | The specific thing people keep filing about |
| A resourcing ask | The allocation that moves, and where it moves from |
| An owner | Someone accountable, named on the slide |
| A gate change | What’ll be scored differently next cycle |
| A disposal | What you’re stopping in order to fund it |
A gap in that list becomes the question you can’t answer in the room. Expect that question to be the one that kills the theme.
Themes Need a Refresh Rate
Once a theme’s approved, the next argument is about pace. McKinsey studied business-unit portfolios, not innovation themes, so treat what follows as suggestive.
Portfolio refresh rate tracked with returns across three bands:
- Under 10 percentage points over ten years: about half the companies studied
- 10 to 30 percentage points over the decade: excess annual TRS higher by 5.2%
- More than 30 percentage points over the decade: excess annual TRS slightly negative
Top performers in that study assign businesses to grow, maintain, or dispose, with different capital rules for each.
Themes take the same treatment. Review them on a fixed cadence, and retire the ones two cycles of data no longer support.
Read the Funnel Before You Write the Strategy
Much of the needed data may already exist inside your organization. Start with the export left untouched since the gate meeting.
Three moves, in this order:
- Export last cycle’s full intake, including everything you killed, and read the distribution before you reread any single idea
- Check the sample: participation rate, which units are missing, and what the campaign prompt actually asked for
- Take two or three candidate themes to a clustering pass, then have humans confirm or reject each one against the raw submissions
At minimum, that takes a decision and staff time; larger or messier datasets may also require tooling or outside support. The decision is that intake counts as evidence.
NewVantage Partners’ 2023 survey found just 24% of respondents called their companies data-driven. Eighty percent named human factors, rather than technology, as the main obstacle.
Next cycle’s strategy gets written either way. The question is whether last cycle’s funnel shows up as evidence, or gets cleared like a queue.
When intake, scoring history, and stage data sit in one place, the second read becomes something you can schedule rather than improvise.
Download our ebook on idea evaluation and governance, or book a demo to see how Accept Mission turns scattered funnel data into portfolio decisions.
Engage Your Circle: Share This Article on
Related Posts


In This Article
How mature is your innovation system?
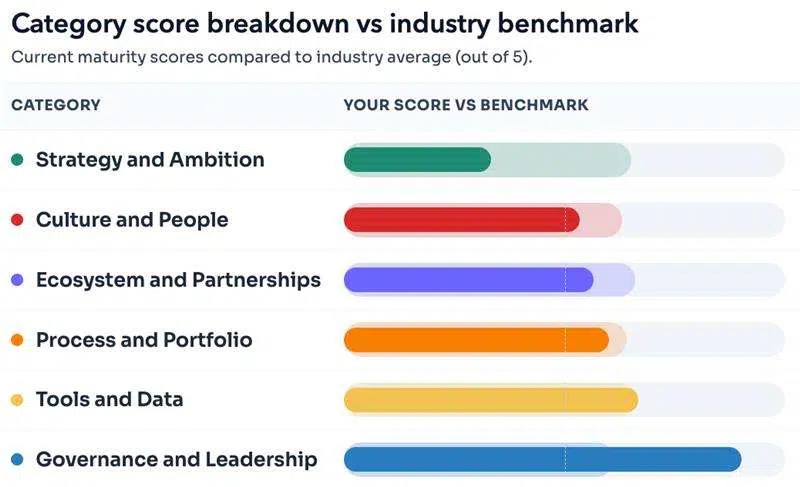
Benchmark your governance, portfolio visibility, and decision making in minutes.
Start the benchmark →



 English
 Dutch
 Portuguese
 Spanish
 French
 German
 Arabic